
A team rewrites the system prompt and swaps from Gemini 2.5 to Sonnet 4.6. The agent feels faster, maybe a little sharper, so the team ships it. Two days later, the support queue fills up because the new version handles edge cases worse. Production traffic just became an uncontrolled experiment.
AI agents are non-deterministic. The same input can produce different outputs across runs. A prompt tweak that improves one category of requests might break another. Unlike traditional software, unit tests cannot cover every possible interaction. Teams need a way to try changes on real traffic, measure the impact, and decide based on data.
That is what A/B testing does. connic now supports controlled experiments on agents. Split traffic between the current version and a variant, compare cost, latency, success rate, and quality scores side by side, then pick the winner with confidence.
Why A/B Test AI Agents
Every change to an AI agent is a hypothesis. "This prompt will be more accurate." "This model will be cheaper without losing quality." "This new tool will speed up responses." A/B testing turns hypotheses into experiments with measurable outcomes.
Run a first agent experiment with connic
Built-in A/B testing routes traffic between agent versions and scores the results, with no separate experimentation tool to wire up.
How It Works
The concept is simple. A base agent is the control, and a variant contains the change under test. Our platform routes a percentage of live traffic to the variant, while the rest continues going to the control. Both versions run in parallel on real requests, and every run is tracked and attributed to its group.
Variant agents are regular agent configurations. They can change anything: the model, the system prompt, the tools, the temperature. A naming convention keeps it obvious which agent is the base and which is the variant:
order-processor.yaml                    # base agent (control)
order-processor-test-faster-model.yaml  # variant: testing a cheaper model
order-processor-test-new-prompt.yaml    # variant: testing a rewritten prompt
Deploy both alongside each other. The variant sits dormant until a test starts routing traffic to it.
What Can Be Tested
Since variants are full agent configurations, the possible experiments are wide open.
name: order-processor-test-faster-model
model: connic/gpt-5.6-luna        # faster, high-volume model
description: "Processes incoming customer orders"
system_prompt: |
  You process incoming orders...
tools:
  - orders.process
  - inventory.check
Everything else stays the same. The variant inherits the exact same workflow. The only difference is the variable under test.
Running a Test
Setting up a test takes less than a minute once the variant is deployed.
Deploy the variant. Push the variant YAML alongside the base agent. After deployment, it shows up as an available test variant.
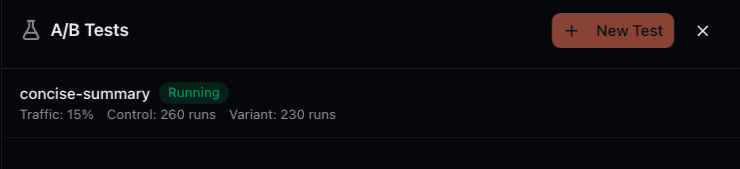
Open the base agent and click Manage A/B Tests in the header.
Create a new test. Pick the variant, set the traffic percentage, and configure a minimum sample size.
Start the test. Tests begin in Draft status so the configuration can be reviewed before going live.
Monitor and conclude. Watch the comparison metrics fill in as runs come through. At the planned sample size and stopping point, compare the results and declare a winner.
Reading the Results
The test detail view provides a side-by-side comparison across every relevant metric:
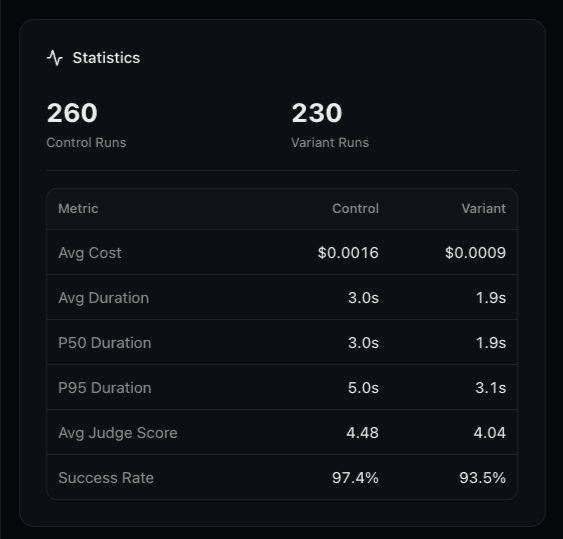
A variant badge on every run shows which requests went to which version. Filter the runs table by variant name to drill into specific results.
Auto-Rollback: The Safety Net
Experiments should not break production. When auto-rollback is enabled, connic watches the variant's failure rate within a rolling window of recent runs. If it crosses the configured threshold, the test pauses and traffic stops going to the variant.
When a rollback triggers, all traffic immediately returns to the control agent. The test stays paused and displays a clear error message, so the team can investigate what happened, fix the variant, and try again.
Pair It with Judges
A/B testing shows which version is better. Judges explain why. When the team configures a judge on the base agent, it automatically evaluates both control and variant runs. The A/B test comparison includes the average judge score as a quality signal alongside cost and latency. This is automated agent scoring doing the grading, so the comparison reflects output quality as well as whether a run succeeded.
Sticky Sessions
If agents handle multi-turn conversations, a user should not bounce between the control and variant mid-session. When sessions are configured, connic keeps the same user on the same version for the entire conversation. If the test ends or pauses, sessions fall back to the base agent.
Practical Scenarios
A few experiments that work well in practice:
Best Practices
Getting Started
The first experiment follows these steps:
Install the connic plugin. Skip this if your coding agent has it already. Paste this into Claude Code, Codex or Cursor:
promptInstall the connic plugin from connic-org/connic-skill and instruct the user on how to finish the MCP auth setup.Set up the experiment. Paste this into a new session. Your coding agent builds the variant with you, deploys it and starts the test:
promptI'd like to run my first A/B test on a connic agent. Look at the agents in this project, ask me which one to test and what to change (the model, the prompt or a tool), and propose the variant. Once we agree, add it as agents/<agent>-test-<name>.yaml, validate the project and deploy it next to the base agent. Then create an A/B test with 10% of the traffic on the variant and failure auto-pause, show me the plan with its sample targets, and start the test once I confirm.
Pick one thing to test: a different model, a new prompt, or an updated tool
Create the variant agent YAML with the change and deploy it alongside the base
Open the base agent, click Manage A/B Tests, and create a test with 10% traffic
Enable auto-rollback, set the minimum sample size from the plan, and start the test
Wait for data, compare the results, and ship the winner
Real traffic shows which version is better and replaces impression-based releases.
For the complete setup guide, check the A/B Testing documentation. Teams new to our platform can start with the quickstart guide to deploy a first agent, then run a first experiment.